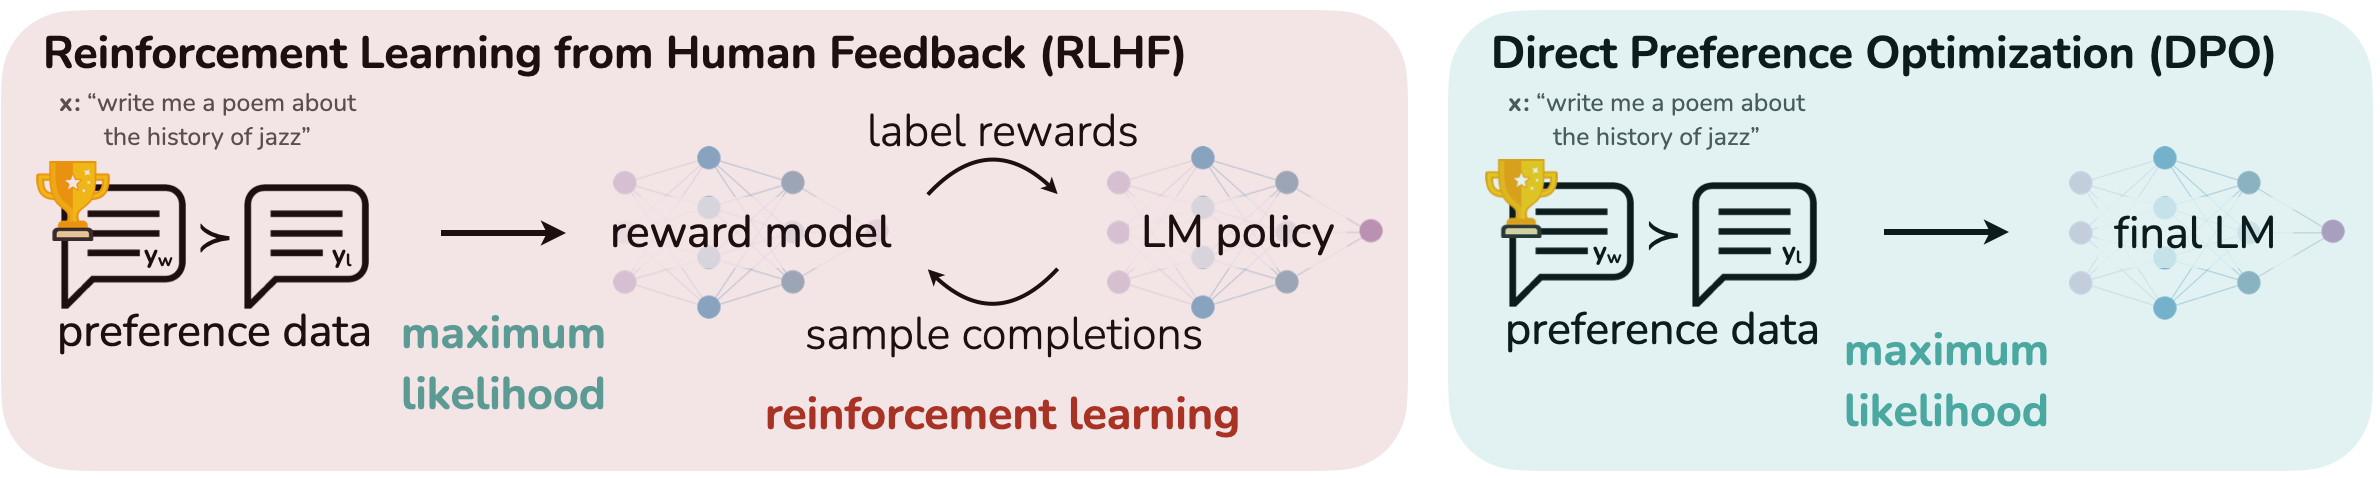
DPO — Direct Preference Optimization: Your Language Model is Secretly a Reward Model
RLHF 要先训一个奖励模型,再用 PPO 在「奖励」上做强化学习——两步、两个模型、还要在训练中反复采样,既贵又不稳。DPO 发现:在 KL 约束下最大化奖励的最优策略有闭式解 $\pi_r \propto \pi_{\text{ref}}\exp(r/\beta)$,把它反解出来就得到 $r=\beta\log(\pi/\pi_{\text{ref}})+\beta\log Z$。奖励只以「差」的形式出现在 Bradley-Terry 模型里,$Z$ 正好抵消——于是「训练奖励模型 + RL」被一个二分类交叉熵损失取代:让「好回答相对差回答的对数概率比」尽量大。梯度还会自动给「判错的样本」…
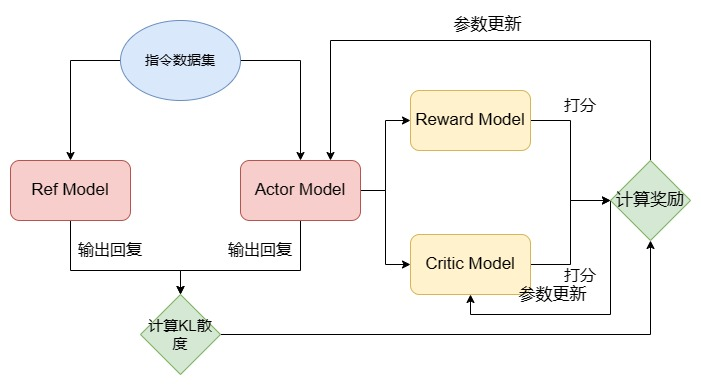
InstructGPT — Training language models to follow instructions with human feedback
Paper reading notes for InstructGPT — Training language models to follow instructions with human feedback.
Recent
Recent